


Your team is probably sitting on a widely shared problem. Answers live in support replies, Slack threads, onboarding calls, old SOPs, and a few people's heads. Everyone knows documentation matters, but knowledge base creation keeps getting treated like a side project that someone will “clean up later.”
That's usually why the first version fails.
A useful knowledge base isn't just a library of articles. It's a content engine. It needs a clear reason to exist, a way to capture what changes, an owner for quality, and a publishing rhythm that survives busy weeks. If you skip those pieces, you don't get a self-service system. You get a folder full of stale articles with search that frustrates people more than silence.
The teams that get this right don't start by obsessing over software. They start by deciding what questions the knowledge base must answer, who needs those answers, and how content will stay current after launch.
Laying the Foundation for a Useful Knowledge Base
The first mistake in knowledge base creation is organizing around your company chart. Users don't care which team owns a process. They care about solving a problem fast.
That's why the architecture has to start with audience and purpose, not internal departments. A useful rule from ServiceNow is to design around how users search, identify recurring questions from support logs, and make sure any article is reachable within two to three clicks to reduce friction (ServiceNow community guidance on knowledge base creation).
Start with three decisions
Before you draft a single article, answer these:
Who is it for
Internal staff, customers, partners, or a mix. If you serve all of them in one place, your language and navigation will collide fast.What job should it do
Reduce repetitive support work, speed up onboarding, standardize operations, or support AI retrieval. Pick the primary job first.What must be true on day one
A launch is successful when users can solve the most common issues without asking around. That usually means a narrow set of high-value content, not a giant unfinished library.
Run short interviews, not endless workshops
You don't need a month of discovery. You need sharp conversations with the people closest to recurring questions.
Use a simple interview pattern:
- Ask support teams which issues they answer repeatedly.
- Ask onboarding or training leads where people stall in their first weeks.
- Ask managers which tasks break when one experienced employee is out.
- Ask end users what terms they type when they're stuck.
Practical rule: If a question shows up in tickets, chat, and training sessions, it belongs in the first publishing wave.
After that, review the evidence. Support inboxes, chat transcripts, internal forum posts, call notes, and failed searches usually tell you more than opinions do.
A lot of teams also hit a tooling decision early. That matters, but only after you've mapped the use case. If you're still comparing options, this breakdown on choosing the right documentation platform is useful because it frames the platform decision around workflow and maintenance rather than feature checklists.
Build a launch list, not a wish list
Don't try to document everything. Create an initial queue of the problems people need solved most often and most urgently. I usually sort them with four filters:
| Filter | What to look for |
|---|---|
| Frequency | Questions that come up repeatedly |
| Impact | Problems that block work or create delays |
| Complexity | Tasks people often do incorrectly |
| Stability | Processes unlikely to change next week |
That gives you a practical opening set of articles. Once you've done that, your knowledge base starts to look less like a random doc collection and more like an operational system. If you need a broader view of how the repository fits into a company's information flow, this overview of a knowledge management system is a useful companion.
Designing Your Content Architecture and Taxonomy
A knowledge base feels smart when the structure disappears. Users shouldn't have to decode your terminology before they can find help.
The easiest way to think about taxonomy is to think like a librarian. Categories are shelves. Sub-categories narrow the shelf. Tags are the index cards that create extra paths across related topics.
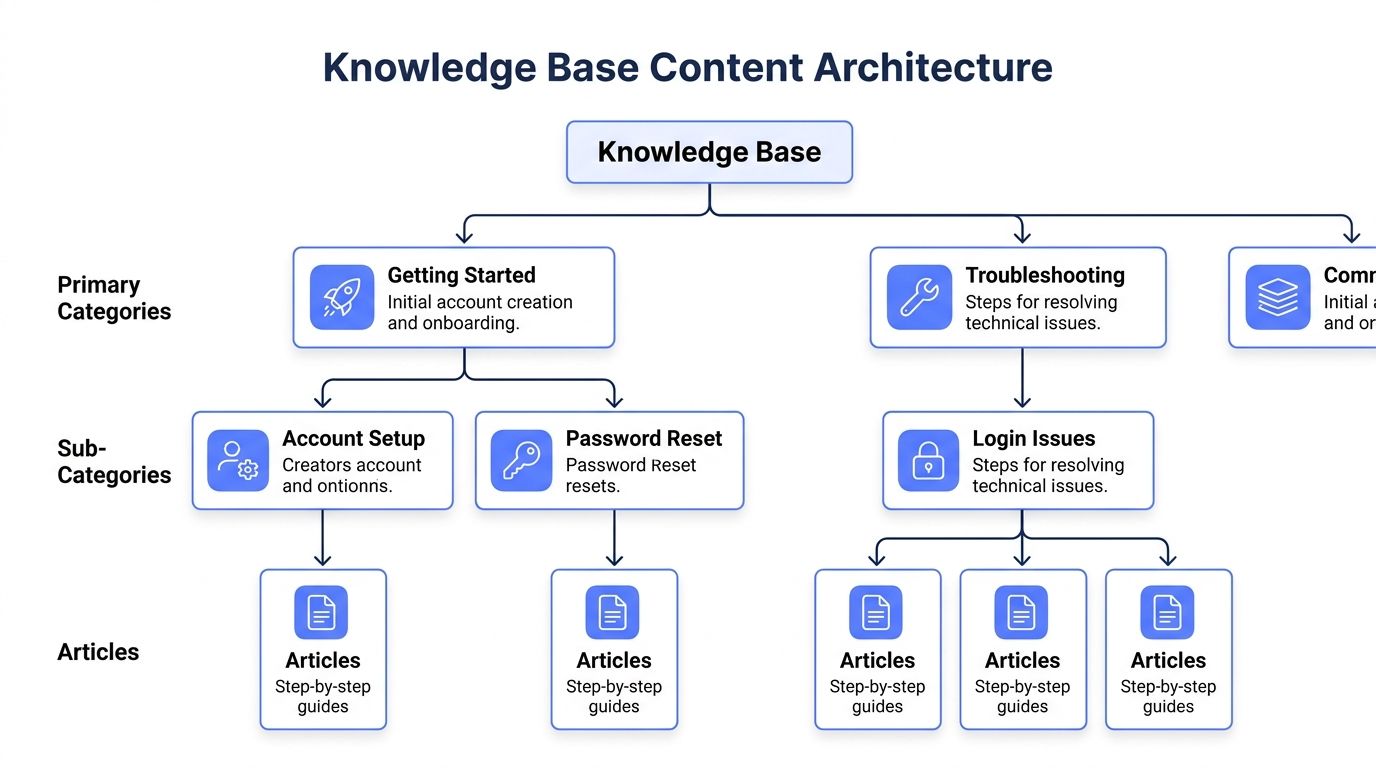
Build categories around user intent
Organizations often create categories like “Admin,” “Billing Team,” or “Platform Operations.” That structure makes sense internally and fails immediately for users.
Better category models sound like this:
- Getting started
- Account access
- Troubleshooting
- Billing and payments
- Integrations
- Policies and permissions
Those names reflect what users want to accomplish or fix. They don't force people to know who owns the answer.
Here's a simple comparison:
| Weak structure | Strong structure |
|---|---|
| Product Features | Set up your account |
| Engineering Docs | Fix login issues |
| Tier 2 Support | Change billing details |
| Operations | Complete month-end workflow |
Keep the hierarchy shallow
Deep trees create dead ends. If users must click through layer after layer, they stop trusting the system and open a ticket instead.
A workable architecture usually has:
- A small set of primary categories that cover the major intents
- Sub-categories only where they remove clutter
- Article titles written as actions or questions, not vague labels
If an article could reasonably live in three different folders, that's a sign your categories are too abstract and your tags need to do more work.
Use tags to create alternate routes
Tags are where a lot of knowledge base creation projects either become flexible or become messy. The trick is to use tags for cross-cutting concepts, not as a dumping ground.
Good tag candidates include:
- product names
- user roles
- workflow stage
- issue type
- related systems
For example, an article about resetting access to a reporting tool might live under Account access, but tags could connect it to finance onboarding, permissions, and troubleshooting.
This matters even more when the same answer supports multiple teams. You don't want duplicate articles that drift apart. You want one maintained article with multiple paths leading to it.
For teams documenting repeatable workflows, this guide on how to organize SOPs is a useful reference because SOP structure and knowledge base taxonomy often need to line up.
Test the structure before you lock it in
A fast way to validate architecture is to hand your draft category list to a few users and ask them where they'd click for five common tasks. Don't explain anything. Just watch.
If people hesitate, misclassify, or choose different routes for the same task, the structure needs work. Good taxonomy usually feels obvious in hindsight. That's the standard you want.
Populating Content Without the Manual Grind
Many knowledge base creation efforts stall here. The strategy is sound, the structure is decent, and then the team hits the main bottleneck. Someone has to write everything.
Manual documentation is slow because it stacks small chores on top of each other. You perform the process, take screenshots, crop them, rename them, write steps, rewrite those steps for clarity, fix formatting, and then update the whole thing when the interface changes.
That's why content production needs a system, not heroic effort. The fastest teams separate capture, editing, and publishing into distinct motions.
Start with article templates
You don't need perfect prose. You need repeatable formats. I recommend three base templates:
| Article type | Best use | Core sections |
|---|---|---|
| How-to | Completing a task | Purpose, prerequisites, steps, expected result |
| Troubleshooting | Fixing a problem | Symptoms, likely causes, resolution steps, escalation path |
| Reference | Clarifying rules or settings | Definition, scope, constraints, related articles |
Templates do two things well. They make content easier to scan, and they reduce editorial debates because people aren't inventing structure from scratch each time.
Still, templates alone don't fix the biggest problem. They don't remove the manual burden of documenting the workflow itself.
Capture the workflow while it happens
This is the shift that changes the economics of documentation. Instead of writing after the fact, modern SOP capture tools record the process as you perform it, preserving clicks, context, and screenshots automatically.
That matters because static documentation breaks easily. The Tutorials Dojo material points to an overlooked issue: 68% of teams struggle with static documentation accuracy, and real-time action logs with smart screenshots can reduce documentation errors by 45% (Tutorials Dojo on Amazon Bedrock knowledge base workflows).
The operational lesson is simple. The closer documentation capture is to the actual task, the fewer details get lost.
Write less from memory. Capture more from the live workflow.
This is also where the broader AI tool ecosystem is helpful to understand. If you're comparing approaches across writing, editing, and media generation, BlitzReels' guide to AI tools is a solid overview of where automation helps and where human review still matters.
Turn writers into editors
The teams that scale documentation well usually stop asking subject matter experts to become writers. That almost never works. Experts know the process, but they rarely have time to narrate every step cleanly.
A better model looks like this:
- Operator performs the process
- Capture tool records actions and visuals
- Editor cleans language and removes noise
- Reviewer approves for accuracy
- Publisher assigns category, tags, and ownership
That workflow is much easier to sustain than “please write a detailed guide when you get a chance.”
For teams building operational documentation at volume, AI-powered SOP generators have changed expectations around speed. Some tools can create SOPs from process descriptions very quickly, with examples ranging from under 30 minutes to under 60 seconds depending on the product and workflow context (XMPro on AI SOP creation; Taskade on SOP generators). The practical takeaway isn't that editing disappears. It's that the bottleneck moves from drafting to review.
A short walkthrough makes the difference clear:
If your team publishes process-heavy help content, it's also worth standardizing the format of your procedural articles. This library of how-to guides is a good benchmark for the level of clarity users expect.
Keep human review where it matters
Automation is strongest at capturing sequence and formatting consistency. Humans still need to check edge cases, permissions, exceptions, and language. Sensitive processes, compliance-heavy workflows, and anything customer-facing need editorial review before publishing.
That's also where AI powered SOP enhancers and an AI powered Knowledge Base generator become relevant. Used properly, they accelerate structuring, polishing, and connecting documentation. Used carelessly, they just help you publish bad information faster.
Launching Your Knowledge Base and Driving Adoption
A knowledge base launch is an internal behavior change project. If you only publish the content and send one announcement, people will ignore it and go back to asking the same questions in chat.
Treat launch week like a product rollout.
Before launch, seed the habits
You need visible use cases before the launch date. The support team should already know which articles to send instead of retyping answers. Managers should know which onboarding tasks now point to the knowledge base. Team leads should know where to report gaps.
A simple pre-launch checklist helps:
- Identify article owners so every high-value article has a person responsible for updates.
- Train frontline teams to link articles during live conversations rather than summarizing from memory.
- Add entry points in the product help menu, onboarding materials, internal portals, or chat shortcuts.
- Prepare a gap log so users can report missing or confusing content without hunting for the right person.
On launch day, focus on access and repetition
Don't introduce the knowledge base as “a new documentation repository.” Introduce it as the fastest place to get answers.
I've found that adoption improves when every announcement shows a direct example. Not “we launched a help center,” but “here's where to reset access, update billing, and follow the new approval workflow.”
The first week should teach one habit. Search here first.
Different teams need different entry points:
| Team | Best adoption move |
|---|---|
| Support | Require article links in common replies |
| HR and L&D | Embed articles in onboarding checklists |
| Operations | Replace scattered SOP attachments with one canonical link |
| Product and success | Route feature questions to relevant articles during calls |
A digital adoption layer can also help if users need guidance inside the application, not just outside it. This overview of a digital adoption platform is useful when your issue isn't lack of documentation but lack of in-context usage.
After launch, market it like an internal service
The launch doesn't end after the announcement. The first month decides whether the knowledge base becomes part of daily work or gets forgotten.
Use recurring reminders that are tied to actual moments of need:
- Weekly highlights featuring newly published or updated articles
- Manager prompts encouraging teams to check the knowledge base before escalating
- Chat shortcuts that surface key articles in common channels
- Email signature links for support or operations staff who answer repeated questions
Watch where users still bypass the system. If they ask in Slack, it may mean the article is hard to find, badly named, or not trusted yet. Adoption work is less about promotion than reducing those points of friction.
Maintaining a Healthy and Trustworthy Knowledge Base
A knowledge base usually loses credibility in a slow, familiar way. A screenshot is outdated. A process changed two weeks ago but the article still shows the old path. Someone follows the steps, gets stuck, and asks a coworker instead. After that, the knowledge base may still be live, but it is no longer trusted.
That is why maintenance needs an operating rhythm, not occasional cleanup. Teams that treat documentation as a continuous process keep trust longer, fix issues faster, and avoid the expensive cycle where people stop using the system and return to Slack, email, or tribal knowledge.
Review cadence beats heroic rewrites
Good maintenance starts with triage. Every article does not need the same level of attention, and trying to review everything on the same schedule usually means nothing gets reviewed well.
A workable model looks like this:
| Content type | Review rhythm | Owner |
|---|---|---|
| High-traffic help articles | Monthly | Support or operations lead |
| Process documentation tied to changing tools | After each product or workflow change | Process owner |
| Broader library audit | Quarterly | Documentation lead or knowledge manager |
This matches what experienced teams already learn the hard way. High-use content breaks trust fastest, while lower-use reference material can wait for a broader audit. ServiceNow recommends monthly checks on top articles and quarterly audits across the wider library. The point is not strict adherence to a calendar. The point is assigning review effort where stale content creates real operational drag.
Track the signals that reveal trust
You do not need a complicated scorecard to spot a healthy knowledge base. A few signals are enough if you review them consistently.
- Self-service resolution and update speed. Librestream reports that effective self-service portals can resolve 60 to 70 percent of support tickets, and teams using dedicated knowledge base software update content faster than teams relying on manual processes (Librestream on self-service knowledge base performance).
- Search failures. Repeated no-result or low-result searches usually point to missing articles, weak titles, or bad taxonomy.
- Article feedback. Helpful and unhelpful votes are useful, but I trust escalation behavior more. If people keep reading an article and still open tickets, the article is not doing its job.
- Time-to-fix for broken content. Fast corrections matter. Users notice when an inaccurate article gets repaired within days instead of sitting untouched for a quarter.
Trust grows through visible maintenance.
Use a governance loop that people can actually run
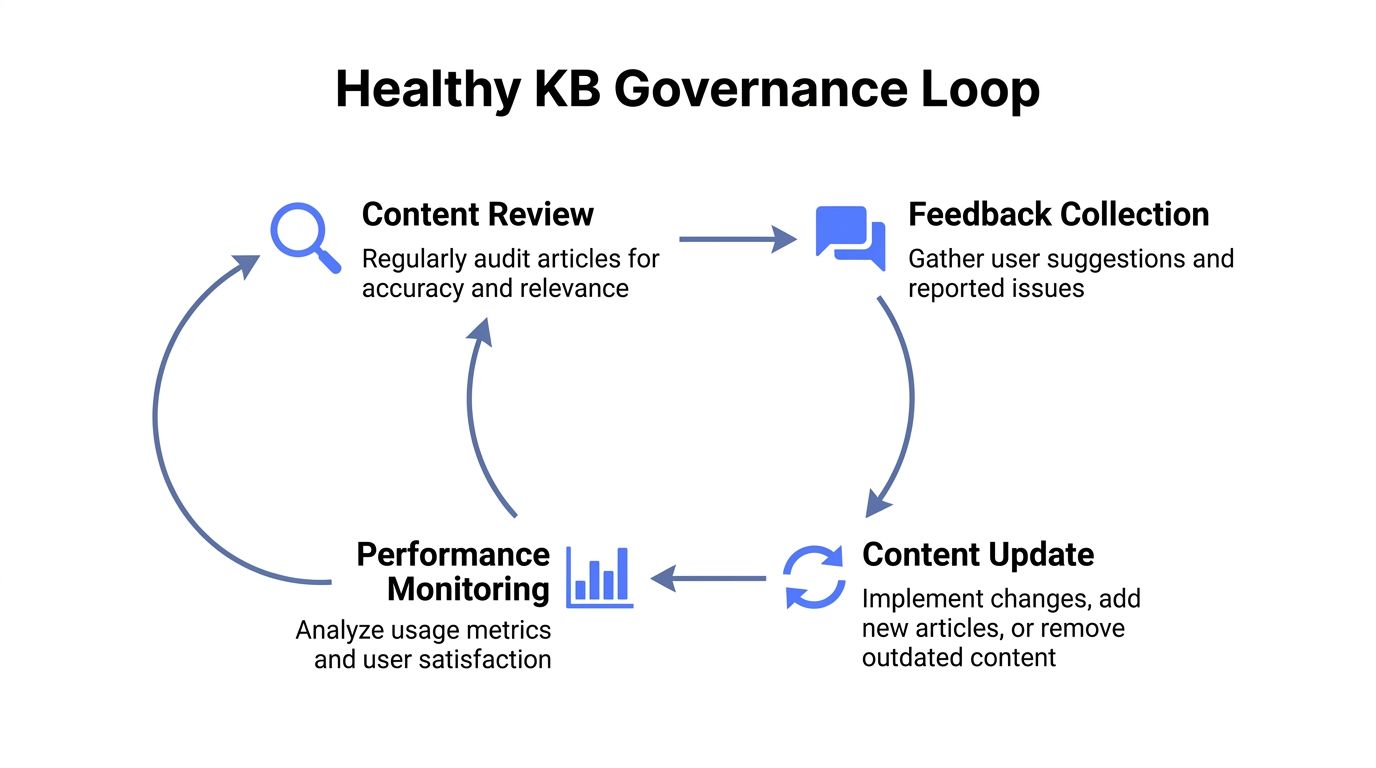
The maintenance loop is simple: review, collect feedback, update, monitor. The challenge is making each step part of normal work instead of a side project.
In practice, that means support flags broken articles during ticket work. Operations owners update process docs when a workflow changes. A documentation lead or knowledge manager checks the backlog, closes gaps, and watches for patterns across teams. That division of labor works better than handing the whole library to one person who becomes the bottleneck.
Here is the loop in plain terms:
Review high-use articles first
Check screenshots, steps, labels, permissions, and links against the current product or workflow.Collect feedback where work already happens
Pull from article ratings, ticket notes, failed searches, chat questions, and frontline complaints.Update quickly
Small fixes done fast are usually worth more than perfect rewrites that take weeks.Monitor whether the fix changed behavior
Look for fewer repeated questions, lower escalation volume, or better task completion after the update.
This is also where AI projects succeed or fail. If your knowledge base feeds assistants, search copilots, or support automation, stale content spreads errors faster. Teams working on AI-powered knowledge strategies need the same discipline, just with higher stakes.
Define ownership in plain terms
Every article should carry three fields:
- Owner
- Last reviewed date
- Trigger for update
The trigger is the field teams skip, and it is often the one that keeps content current. Good triggers are tied to real events: pricing changes, a product release, a policy revision, a new permissions model, or a workflow handoff.
I have seen teams improve article freshness just by adding that one line. It removes the vague question of when someone should revisit a page and replaces it with a specific operational trigger. That is how a knowledge base stays trustworthy over time.
From Project to Living Resource
The best knowledge base creation work doesn't end at publication. It gets stronger because the team keeps feeding it better input, cleaner structure, and fresher process knowledge.
That's the mindset shift necessary. A knowledge base isn't a one-time migration project. It's a product with users, workflows, maintenance costs, and measurable outcomes. It supports self-service, reduces repeated explanations, standardizes how work gets done, and gives AI systems something reliable to work from.
Perfection on day one is the wrong target. Start with the questions people ask every week. Publish the answers in a structure users can understand. Give each article an owner. Review what breaks. Improve what people use.
If you do that consistently, the knowledge base stops being a documentation exercise and becomes operating infrastructure. That's when it starts saving time for support, onboarding, operations, and everyone else who depends on clear answers.
If you want a faster way to turn live workflows into clear documentation, StepCapture is built for exactly that. It records actions as you work, helps teams create SOPs and help content quickly, and supports both AI powered SOP enhancers and an AI powered Knowledge Base generator so your team can spend less time writing from scratch and more time reviewing, organizing, and publishing useful knowledge.


